
Updated October 2026
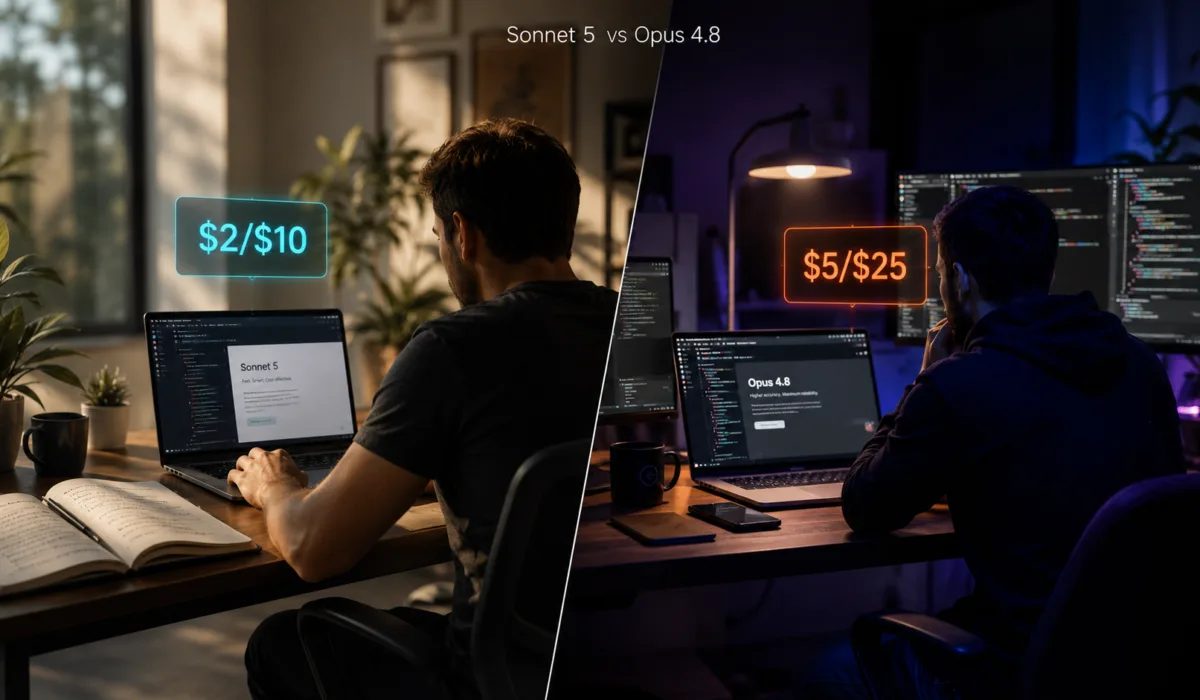
When Anthropic released Claude Sonnet 5 on June 30, 2026, it made the Sonnet versus Opus decision harder than it had ever been.
Before then, the choice was simple: Opus for serious work, Sonnet for everything else. Sonnet 5 changed that. Anthropic described its performance as close to Opus 4.8 at a much lower price, and on one benchmark it scored slightly higher than the flagship.
If you’re comparing Claude Sonnet 5 vs Opus 4.8 for your workflow, the wrong choice either costs you 2.5 times more per token than necessary, or leaves capability on the table when your work genuinely needs it.
Here’s the analyst breakdown, based on Anthropic’s published benchmarks and pricing, plus what has changed since both models launched.
October 2026 Update: Opus 4.8 Is Now a Legacy Model
Two things have changed since this Claude Sonnet 5 vs Opus 4.8 comparison first ran, and both matter for your decision.
Opus 4.8 has moved to Anthropic’s legacy list. Anthropic released Claude Opus 5 over the summer and now points new work at its newer Opus models, according to Morph’s Opus 4.8 guide. Then on September 22, it released Claude Opus 5.5 at $4/$20 per million tokens, cheaper than Opus 4.8’s $5/$25.
Sonnet 5’s price is now permanent. Sonnet 5 launched at an introductory $2/$10 that was due to rise to $3/$15 after August 31. Anthropic’s announcement now confirms the $2/$10 price became permanent on August 10.
So if you’re choosing a model today, the real comparison is Sonnet 5 vs Opus 5.5, which we cover in its own section below. If you already run Opus 4.8 in production, this guide helps you decide whether Sonnet 5 can take over part or all of that work.
The 30-Second Verdict on Claude Sonnet 5 vs Opus 4.8
Default to Claude Sonnet 5. It’s Anthropic’s most agentic Sonnet model yet, costs $2/$10 per million tokens, and performs close to Opus 4.8 on most benchmarks at 40% of the price.
Escalate to Opus when your task involves the hardest multi-file coding, deep debugging, complex reasoning, or legitimate cybersecurity work, where Anthropic specifically recommends Opus over Sonnet 5.
If you’re starting fresh, escalate to Opus 5.5 rather than Opus 4.8. It’s newer, stronger and cheaper.
For most production workflows, Claude Sonnet 5 vs Opus 4.8 isn’t really a contest. It’s a cost-performance dial. Set it by matching the model to the task, not by defaulting to the flagship.
The Benchmark Comparison: Claude Sonnet 5 vs Opus 4.8
Here’s what the published Claude Sonnet 5 vs Opus 4.8 numbers show, using only figures that independent summaries report consistently.
| Benchmark | Claude Sonnet 5 | Claude Opus 4.8 | Gap |
|---|---|---|---|
| SWE-bench Pro (agentic coding) | 63.2% | 69.2% | Opus +6.0 |
| SWE-bench Verified (coding) | 85.2% | 88.6% | Opus +3.4 |
| Humanity’s Last Exam (with tools) | 57.4% | 57.9% | Effectively tied |
| GDPval-AA v2 (knowledge work) | 1,618 | 1,615 | Sonnet +3 |
Sources: Eden AI’s benchmark comparison and Emergent’s score breakdown.
Sonnet 5 also scores 80.4% on Terminal-Bench 2.1 and 81.2% on OSWorld-Verified. Published figures for Opus 4.8 on those two benchmarks vary from source to source, likely because they come from different charts and settings, so we’ve left them out of the table rather than pick one.
Two findings stand out.
First, Sonnet 5 matches Opus 4.8 on knowledge work. GDPval-AA measures applied professional tasks like document analysis, research synthesis and structured output. Sonnet 5 scores marginally higher. If your work is mostly analysis, research or document processing, Sonnet 5 is effectively equivalent.
Second, Opus 4.8 still leads on the hardest coding. The 6-point gap on SWE-bench Pro is the widest in the table. That’s where Opus earns its premium: difficult multi-step engineering, complex debugging and hard reasoning.
Between those two, the Claude Sonnet 5 vs Opus 4.8 comparison shows close performance at very different prices. As always, these are vendor-published results. Our guide on how to read AI benchmarks explains why you should test on your own tasks before trusting any single score.
Claude Sonnet 5 vs Opus 4.8 Pricing
The price gap is where the Claude Sonnet 5 vs Opus 4.8 decision gets real.
| Claude Sonnet 5 | Claude Opus 4.8 | Claude Opus 5.5 | |
|---|---|---|---|
| Input (per 1M tokens) | $2 | $5 | $4 |
| Output (per 1M tokens) | $10 | $25 | $20 |
| Cost vs Sonnet 5 | Baseline | 2.5x | 2x |
| Status | Current | Legacy | Current |
Prices are from Anthropic’s pricing page and Benchlm’s API pricing tracker. Our Claude pricing guide covers every plan and rate.
The practical math. An agent workload costing $1,000 a day on Opus 4.8 would cost about $400 a day on Sonnet 5 and $800 on Opus 5.5. For a team sending 10 million input and 2 million output tokens a month, that’s $100 on Opus 4.8, $80 on Opus 5.5 and $40 on Sonnet 5.
Both prompt caching and batch processing apply to all three models. Batch jobs that can wait up to 24 hours cost 50% less, and cached input costs a small fraction of the normal rate. But the base rate still sets the floor, and Sonnet 5’s is 60% lower than Opus 4.8’s.
One detail to budget for. Sonnet 5 uses an updated tokenizer, and Anthropic says the same text can map to roughly 1.0 to 1.35 times as many tokens, depending on the content. If you’re moving from an older Sonnet model, measure token counts on your real prompts before finalizing a budget.
Claude Sonnet 5: What You Get
Anthropic positions Sonnet 5 as its most agentic Sonnet model. In its own words, Sonnet 5 can make plans, use tools like browsers and terminals, and run autonomously at a level that only recently required larger, more expensive models.
It supports a 1 million token context window and an adjustable effort setting, so you can trade speed and cost against depth of reasoning.
Where Sonnet 5 shines:
- High-volume production. At $2/$10, Sonnet 5 makes production AI applications affordable at scale.
- Agentic tasks below the frontier. Browser automation, terminal work, multi-step tool use and customer-facing assistants.
- Knowledge work. With its GDPval-AA result, Sonnet 5 delivers Opus-level quality on document analysis, research synthesis and structured output.
- Prototyping. Build on Sonnet 5 first. You’ll often find it handles more than you expected before you ever need Opus.
- Real-time applications. Smaller models generally respond faster, which matters for user-facing tools.
The trade-offs:
- Not frontier capability on the hardest tasks. The SWE-bench Pro gap is real for difficult engineering work.
- Deliberately limited cybersecurity ability. Anthropic says it didn’t train Sonnet 5 on cybersecurity tasks and that it performs substantially worse than Opus 4.8 on dangerous cyber skills. For legitimate security work, Anthropic recommends Opus.
- High effort erodes the savings. Running Sonnet 5 at its highest effort setting uses many more tokens, which narrows the cost advantage. The best value usually comes from lower effort levels.
Claude Opus 4.8: When It Was Worth Paying For
Opus 4.8 launched on May 28, 2026 as Anthropic’s flagship for daily agentic work, at $5/$25 per million tokens with a 1 million token context window and up to 128,000 output tokens per request.
Where Opus 4.8 shines:
- The hardest agentic coding. Multi-file repository work, long-horizon engineering and complex refactors.
- Deep debugging. When Sonnet keeps circling a hard bug, a stronger model often breaks the loop.
- Cybersecurity work. Anthropic specifically recommends Opus 4.8 for security work that needs reduced guardrails.
- Long outputs. 128,000 output tokens per request suits long reports and large code generation.
- Accuracy-critical work. Financial, legal and research tasks where a few points of accuracy matter.
The trade-offs:
- 2.5 times Sonnet 5’s price on both input and output.
- Legacy status. Anthropic now steers new work toward its newer Opus models.
- Overkill for high-volume work. Running Opus on tasks Sonnet handles well wastes budget.
If you’re running Opus 4.8 today, the question isn’t whether it’s capable. It’s whether Opus 5.5 does the same work for less, and whether Sonnet 5 can take the routine share entirely.
Sonnet 5 vs Opus 5.5: The Comparison That Matters Now
For new projects in late 2026, the Opus choice is Opus 5.5, not Opus 4.8.
Opus 5.5 costs $4/$20 per million tokens, exactly twice Sonnet 5’s price. Anthropic positions it at the level of its Mythos-class Fable 5.1 on most work, and it ranked first on Artificial Analysis’s independent Intelligence Index at launch. It also has a 1 million token context window with no long-context surcharge.
That makes escalation cheaper than it used to be. Opus 5.5 is both stronger and cheaper than Opus 4.8, so the premium for moving up from Sonnet has shrunk from 2.5 times to 2 times. The logic stays the same: default to Sonnet 5, and escalate to Opus 5.5 only for work Sonnet can’t handle.
One warning before switching from Opus 4.8: Opus 5.5 introduced breaking API changes that can cause errors in integrations upgraded without code changes. Our Claude Opus 5.5 pricing guide lists all four with a migration checklist.
The Claude Sonnet 5 vs Opus 4.8 Decision Framework
Use Claude Sonnet 5 when:
- Per-token cost affects your margins
- The task is standard difficulty: routine coding, research, content or document analysis
- You need fast responses for user-facing applications
- You’re prototyping before committing to Opus pricing
- The work is mostly knowledge work, where Sonnet 5 matches Opus
Use Opus (4.8 if you’re already on it, 5.5 if you’re starting fresh) when:
- The task is genuinely difficult coding, like multi-file refactors or hard debugging
- You need deep reasoning on hard problems
- The work is legitimate cybersecurity research
- You need very long outputs in a single request
- Accuracy justifies paying 2 to 2.5 times more
- You keep hitting Sonnet 5’s ceiling on a specific workflow
The hybrid approach most production teams should use: route routine tasks to Sonnet 5 at a lower effort setting, and escalate hard tasks to Opus. Adjust the split based on your bill and your quality bar.
For Claude Code users, a simple pattern works well:
- Default to Sonnet 5 while building and iterating
- Switch to Opus when Sonnet stalls on a difficult problem
- Reserve Fable 5.1 for long autonomous sessions that genuinely need Mythos-class capability
Don’t leave Opus running by default, whichever side of the Claude Sonnet 5 vs Opus 4.8 split you start from. It uses plan limits and API budget much faster than Sonnet for routine work.
Real Workflows: Which Model Wins Where?
Beyond the benchmark table, here’s how Claude Sonnet 5 vs Opus 4.8 plays out on actual workloads.
Customer support chatbots: Sonnet 5. Lower cost, faster responses, and capable enough for most support conversations.
Content generation at scale: Sonnet 5. Content rarely needs frontier reasoning, and $2/$10 keeps production volume affordable.
Complex multi-step engineering: Opus. The SWE-bench Pro gap shows up in real work as fewer failed attempts.
Data analysis and business intelligence: Sonnet 5. It matches Opus on knowledge work at a fraction of the price.
Legal document review: depends on the stakes. Opus for high-stakes work where errors are expensive, Sonnet 5 for routine review.
Day-to-day coding in Claude Code: Sonnet 5 for most work, Opus for broad refactors, hard debugging and architecture decisions.
Real-time voice or streaming: Sonnet 5. Speed matters more than the last few points of benchmark performance.
Cybersecurity research: Opus. Anthropic deliberately limited Sonnet 5’s cyber capability.
The Alternatives to Claude Sonnet 5 vs Opus 4.8
The Claude Sonnet 5 vs Opus 4.8 debate assumes you’re staying with Anthropic. For many workflows, other options are worth testing.
OpenAI’s GPT-6 Sol costs $2/$10 per million tokens, the same as Sonnet 5, and is the natural head-to-head. GPT-6 Luna, at $0.10/$0.50, is far cheaper for simple high-volume tasks. See our GPT-6 pricing guide and GPT-6 vs Claude Opus 5.5 comparison.
Claude Haiku 4.5, at $1/$5, handles classification, extraction and short replies at half Sonnet’s price.
MiniMax and GLM compete on price for speed-sensitive and Chinese-language workloads. Test them on your own tasks, since performance varies widely by use case.
Multi-model platforms like Aymo AI bundle access to many models for a flat monthly fee, which can suit solo professionals and small teams.
For the frontier tier, see our Claude Fable 5 vs Opus 4.8 vs Sonnet 5 comparison.
Which Claude Plan Should You Use?
Free: good for testing Claude’s basic capabilities.
Pro ($20/month, or $17 billed annually): access to Sonnet, Opus and Haiku with usage limits, plus Claude Code. Best for individual professionals.
Max ($100 or $200/month): much higher usage limits for people who consistently hit Pro’s caps.
Team ($25 per seat per month, or $20 billed annually; Premium seats $125 or $100): central billing and higher limits for groups of 2 to 150 people.
Enterprise: custom pricing with security controls, an annual contract and usage billed at API rates.
Plan details are from Benchlm’s plan breakdown. Start with Pro and move up only when you consistently hit its limits. For production applications, the pay-as-you-go API is usually the better fit.
FAQs
1. Is Claude Sonnet 5 as good as Opus 4.8?
For most workloads, it’s close. Anthropic describes Sonnet 5’s performance as close to Opus 4.8 at lower prices, and on knowledge work (GDPval-AA v2) Sonnet 5 scores slightly higher. Opus 4.8 still leads on the hardest coding, with a 6-point advantage on SWE-bench Pro.
2. Is Claude Sonnet 5’s $2/$10 price permanent?
Yes. Sonnet 5 launched at an introductory $2/$10 that was due to rise to $3/$15 after August 31, 2026. Anthropic made $2/$10 permanent on August 10, 2026.
3. Is Opus 4.8 still available?
It’s on Anthropic’s legacy model list. Anthropic points new work toward its newer Opus models, and Opus 5.5, released September 22, 2026, costs less than Opus 4.8 at $4/$20 per million tokens.
4. Can Claude Sonnet 5 replace Opus for coding?
For most coding, yes. Sonnet 5 is a strong default for day-to-day work in Claude Code. Keep Opus for the hardest multi-step engineering, complex refactors and difficult debugging, where the SWE-bench Pro gap matters.
5. Why isn’t Sonnet 5 recommended for cybersecurity work?
Anthropic says it didn’t deliberately train Sonnet 5 on cybersecurity tasks, and that Sonnet 5 performs substantially worse than Opus 4.8 on dangerous cyber skills. For legitimate security work that needs reduced guardrails, Anthropic recommends Opus 4.8.
6. What is the Sonnet 5 tokenizer change?
Sonnet 5 uses an updated tokenizer that can turn the same text into roughly 1.0 to 1.35 times as many tokens, depending on the content. Real costs can be slightly higher than a price comparison alone suggests, so measure token counts on your own prompts.
7. Should I choose Sonnet 5 or Opus 5.5?
Default to Sonnet 5 and escalate to Opus 5.5 for difficult work. Opus 5.5 costs exactly twice Sonnet 5’s price and is Anthropic’s strongest Opus model, so it’s the better escalation path than Opus 4.8 for any new project.
Final Verdict on Claude Sonnet 5 vs Opus 4.8
The Claude Sonnet 5 vs Opus 4.8 question has a clear answer: default to Sonnet 5, and escalate to Opus only when a specific task justifies paying 2 to 2.5 times more.
Sonnet 5 performs close to Opus 4.8 on most benchmarks, matches it on knowledge work, and costs 60% less. That’s not a marginal improvement. It’s a structural shift in what Sonnet-tier pricing can do.
Opus still has a clear role, but a narrower one: the hardest coding, deep debugging, complex reasoning, cybersecurity and very long outputs. And with Opus 4.8 now on the legacy list, that role belongs to Opus 5.5 for anyone starting fresh.
The winning strategy isn’t picking one model. It’s routing between them based on task difficulty and cost. Do that well, and your Claude bill drops substantially without a meaningful loss in quality.
Mahdi Ayadi writes and edits AI Empire Media. He covers AI models, tools and pricing with one question in mind: is this actually worth paying for?
Before writing about software, Mahdi spent more than seven years selling it, in B2B SaaS sales and account management across cybersecurity, marketing technology and travel technology. That experience shapes how he reads vendor pricing pages, benchmark claims and feature lists, and it’s why his articles focus on real costs, trade-offs and sources readers can check for themselves.
He also builds AI-powered automation for sales and onboarding workflows, which informs his coverage of AI agents and automation tools. He works in English, French, Arabic and Russian.